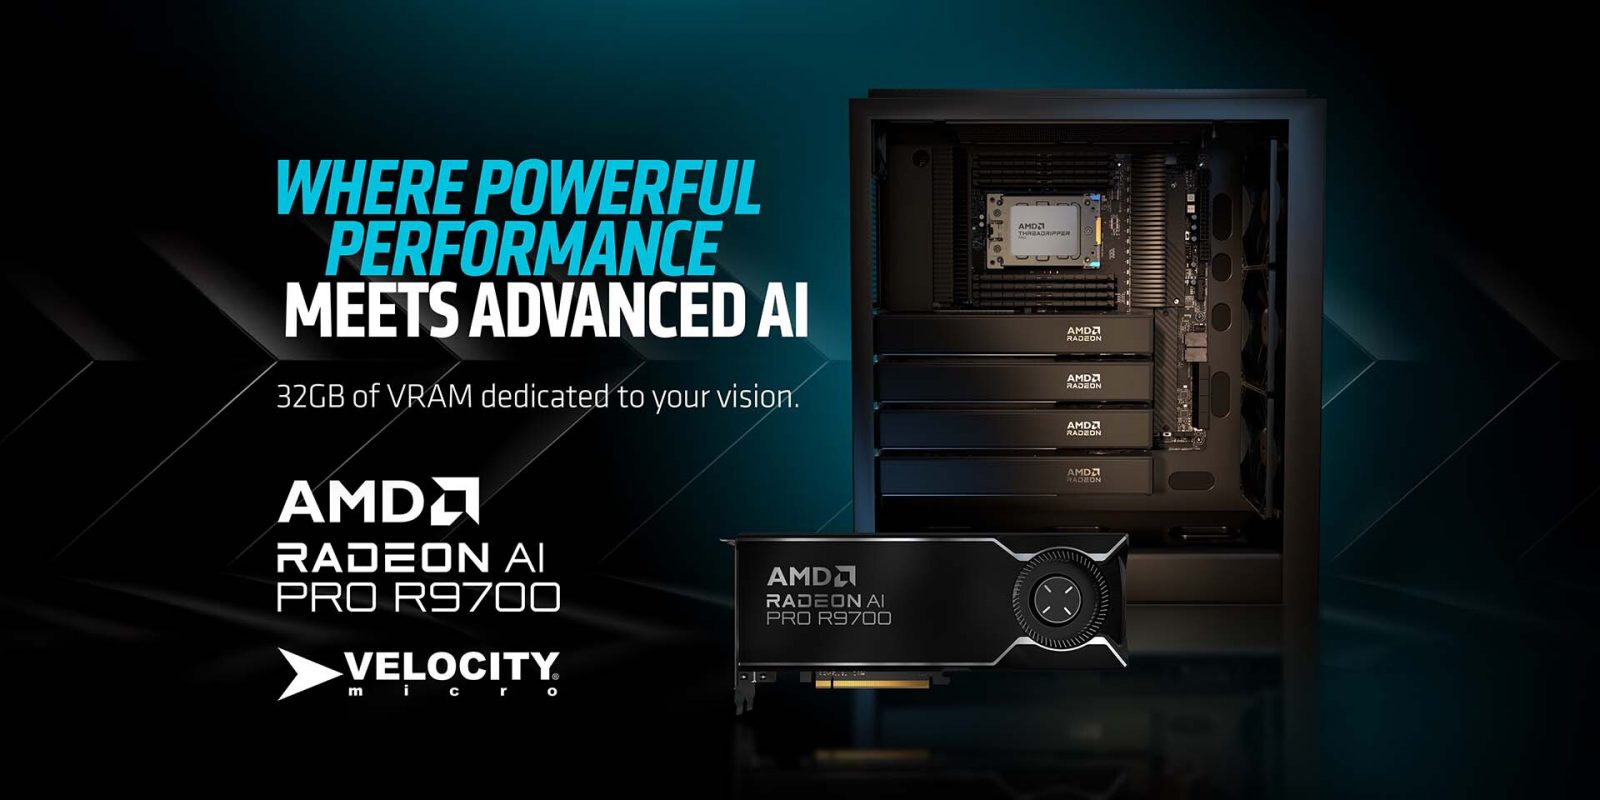
Redefining Local AI Performance
As AI development increasingly shifts from cloud to local environments, professionals are running into a significant barrier—video memory. Modern large language models (LLMs) like DeepSeek R1, Mistral 3.1, and Flux.1 require more than 20GB of VRAM to run smoothly. Consumer-grade GPUs with 16GB or less often fall short, leading to sluggish performance, model incompatibility, or the need to offload tasks to slower system memory.
Enter the AMD Radeon™ AI PRO R9700—a professional-grade GPU built specifically to meet the demands of local AI workloads. Featuring the new AMD RDNA™ 4 architecture and a generous 32GB of GDDR6 memory, the R9700 delivers the throughput and compute power required for next-gen AI development, simulation, and generative workflows.
Built for Local AI at Scale
The Radeon™ AI PRO R9700 is equipped with:
| Specification | Details |
|---|---|
| Compute Units | 64 |
| VRAM | 32GB GDDR6 |
| Memory Interface | 256-bit |
| Memory Bandwidth | 640 GB/s |
| AI Accelerators | 128 |
| FP16 Dense Performance | 191 TFLOPS |
| INT4 Sparse Performance | 1531 TOPS |
| Power Draw (TDP) | 300W |
| Interface | PCIe® 5.0 |
That massive 32GB VRAM buffer is the game-changer here. It’s not just about storing more data—it’s about enabling high-performance inference and training for increasingly demanding models without offloading to system RAM.
Performance Comparison: AMD Radeon AI Pro 9700 vs NVIDIA RTX 5080
In benchmark testing using models like Phi 3.5 MoE, DeepSeek R1, and Qwen 3 32B Q6, the Radeon™ AI PRO R9700 dramatically outpaced NVIDIA’s GeForce RTX 5080 (16GB). For large prompts and high-parameter models, the Radeon card posted up to 496% faster throughput in tokens/sec—a critical metric in LLM performance.
Token Throughput Benchmark (Higher is Better)
| Model / Prompt | RTX 5080 (16GB) | Radeon AI PRO R9700 (32GB) | Performance Uplift |
|---|---|---|---|
| Phi 3.5 MoE Q4 | 100% (baseline) | 361% | +261% |
| Mistral Small 3.1 24B Instruct 2503 Q8 | 100% (baseline) | 437% | +337% |
| Qwen 3 32B Q6 (Standard Prompt) | 100% (baseline) | 447% | +347% |
| DeepSeek R1 Distill Qwen 32B Q6 | 100% (baseline) | 454% | +354% |
| Qwen 3 32B Q6 (Large Prompt >3000 tokens) | 100% (baseline) | 496% | +396% |
Source: AMD RPW-495 Benchmarks, May 2025
The takeaway? For professionals running large prompts or full-sized models locally, the Radeon™ AI PRO R9700 isn’t just competitive—it’s transformative.
Ideal Use Cases for Radeon AI PRO R9700
The AI PRO R9700 is designed for professionals and researchers working in:
- Large Language Model Development – Fine-tune and test LLMs like Qwen, Mistral, and DeepSeek locally without cutting model size or performance.
- Generative Design & Simulation – Run CAD simulations or generative AI workflows without offloading compute to the cloud.
- AI-Driven Content Creation – Utilize advanced text-to-image tools like Stable Diffusion 3.5 Medium, which requires more than 20GB of VRAM.
With native support for the AMD ROCm™ framework, the card is optimized for deep learning frameworks like PyTorch, enabling broader compatibility across AI pipelines.
Multi-GPU Scalability & Form Factor Advantage
One key strength of the AI PRO R9700 is its suitability for multi-GPU workstation deployments. The compact form factor combined with PCIe® 5.0 compatibility means users can scale up performance by adding additional cards—critical for inference farms or training setups where concurrency matters.
Conclusion: A Smart Bet for AI-First Professionals
The AMD Radeon™ AI PRO R9700 is more than a professional GPU—it’s a platform for pushing the boundaries of local AI. With 32GB of VRAM, 128 AI accelerators, and incredible token-per-second performance, it’s purpose-built for the future of machine learning and large model development on the desktop.
For professionals seeking a high-throughput, scalable, and cost-effective alternative to cloud compute or memory-limited GPUs, the R9700 is a compelling new benchmark. Get yours on our ProMagix HD150 now.